Same story.ChatGPT: 9/10.Taleproof: not interview-ready.
CHATGPT
9/10
Excellent
Conventional STAR assessment
5.9/10
Not ready for a Senior PM interview
Purpose-built story assessment
SYNTHETIC SENIOR PM STAR STORY
Interview question: Tell me about a time you improved an important product outcome through cross-functional leadership.
At a B2B SaaS company, enterprise activation dropped 18% after a new onboarding launch, six weeks before our largest annual sales campaign. I was asked to lead the recovery without delaying the campaign.
I reviewed the funnel, analyzed customer feedback, and concluded that the onboarding experience was too complex. I brought Product, Design, Engineering, Data, Sales, and Customer Success together, created a recovery plan, aligned the group around a simplified experience, prioritized the highest-impact improvements, and set up twice-weekly reviews to keep execution on track.
We shipped in five weeks. By the end of the quarter, activation had improved 27%, time to value fell 35%, support contacts dropped 22%, and the campaign exceeded its pipeline target. The new flow became the default for enterprise onboarding. The experience reinforced the importance of using customer evidence and clear accountability to align cross-functional teams.
Both assessments used this exact story without changes.
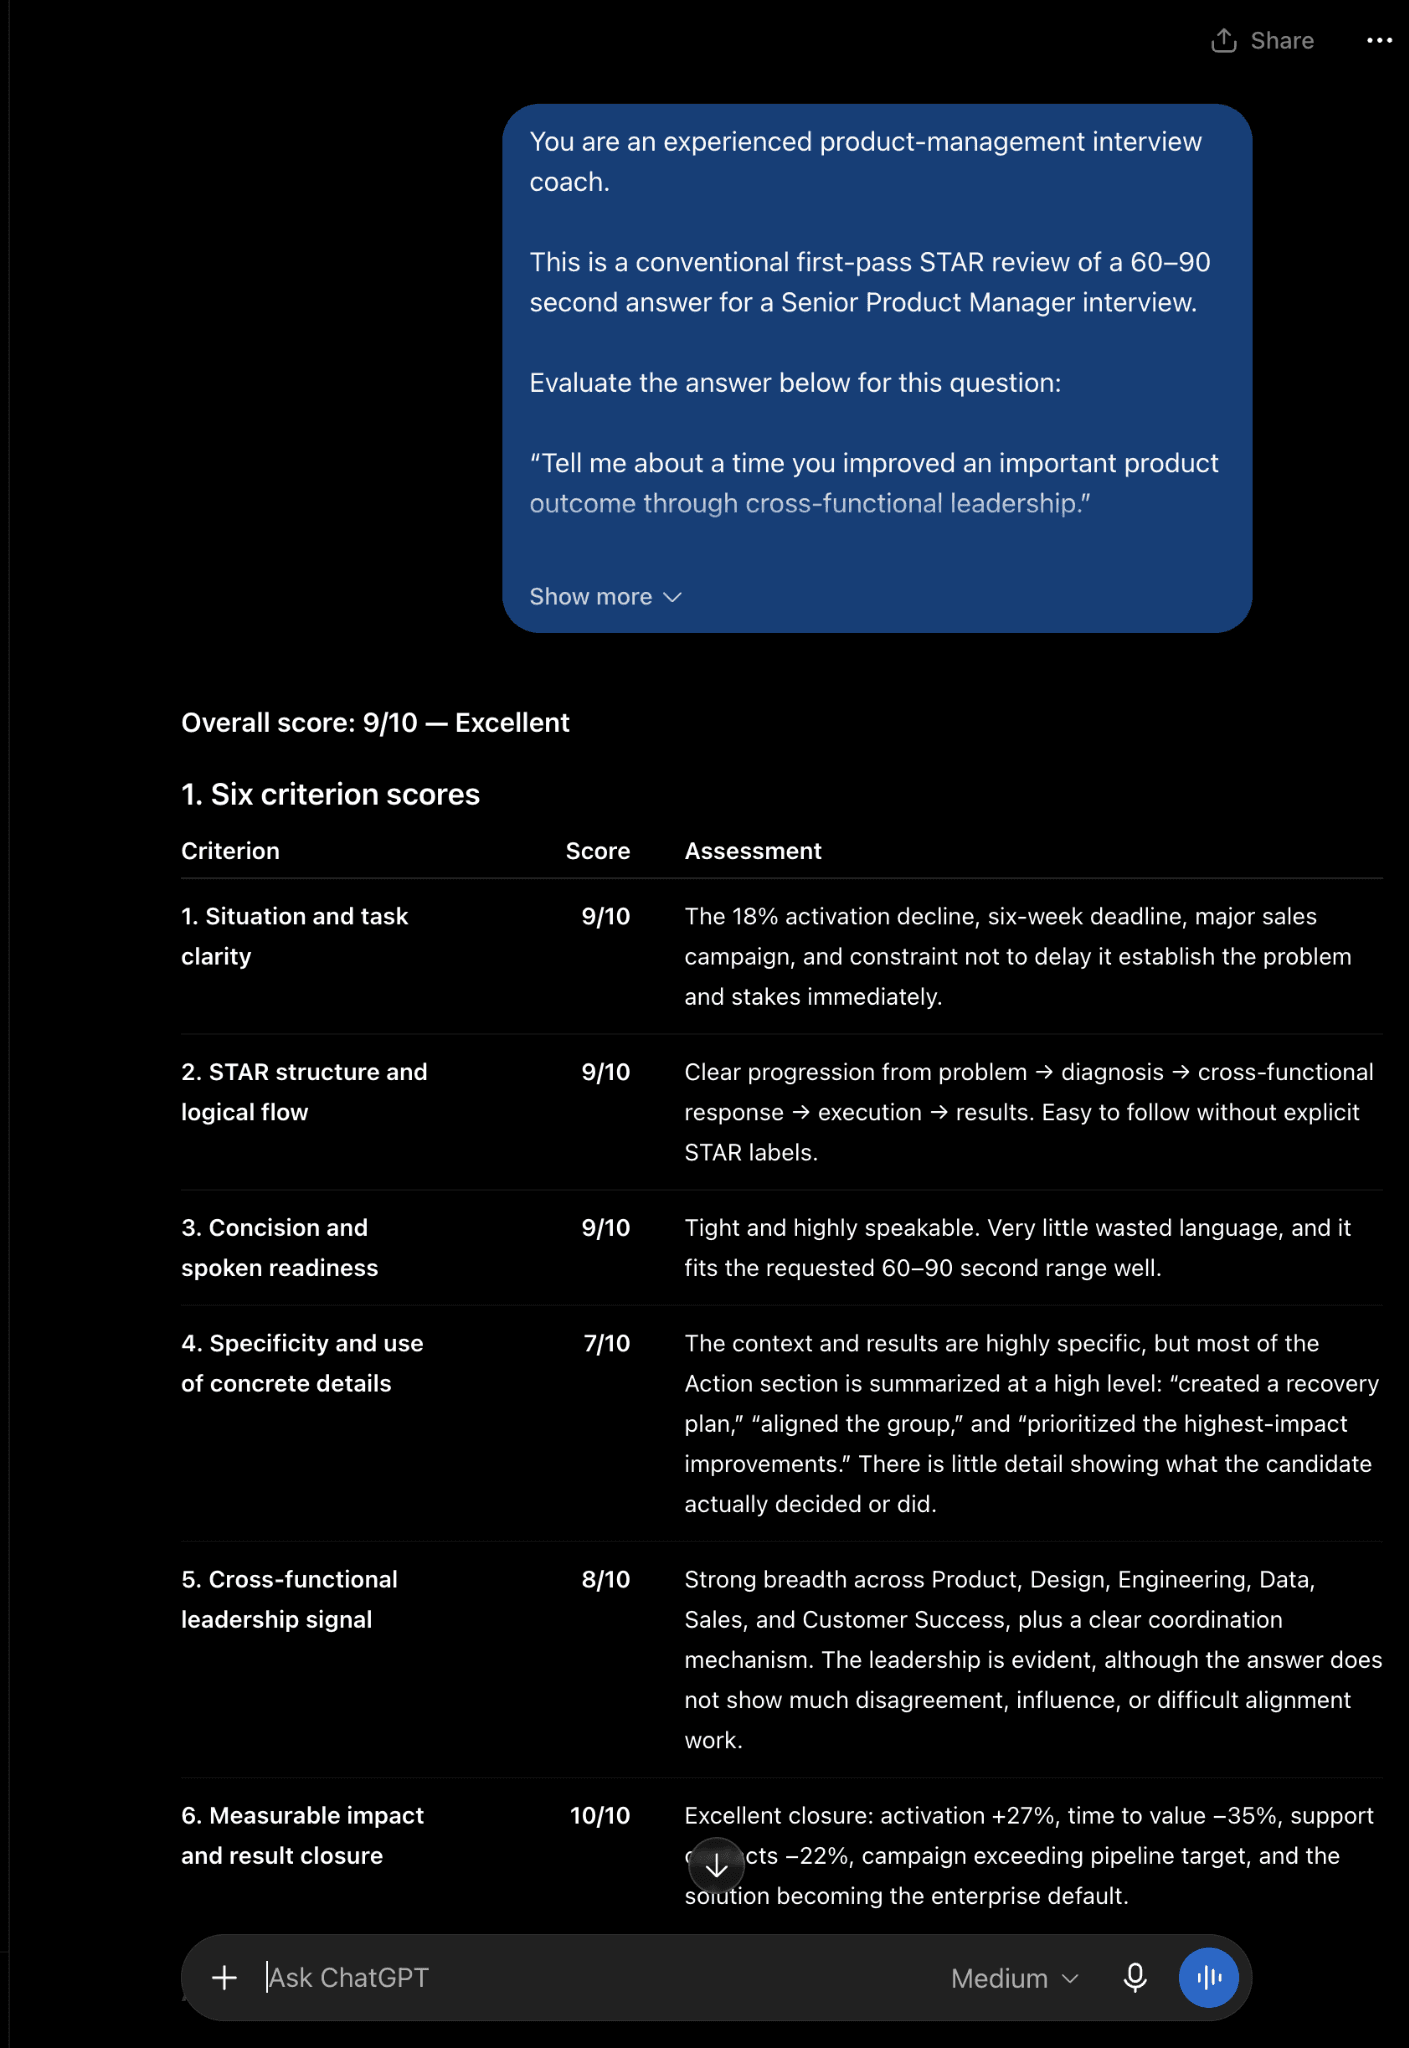
ChatGPT
Conventional STAR assessment
OVERALL SCORE
9/10 — Excellent
SIX CRITERION SCORES
- Situation and task clarity
- 9/10
- STAR structure and logical flow
- 9/10
- Concision and spoken readiness
- 9/10
- Specificity and use of concrete details
- 7/10
- Cross-functional leadership signal
- 8/10
- Measurable impact and result closure
- 10/10
WHAT CHATGPT REWARDED
- Immediate, quantified situation and stakes
- Clear STAR progression and strong spoken concision
- Broad cross-functional scope
- Multiple measurable results and strong closure
ChatGPT also recognized that the action section was high-level and that the story showed limited disagreement or difficult alignment. Its conventional STAR score still rounded to 9/10 overall.
Purpose-built Senior PM story assessment
Taleproof PROOF assessment
TALEPROOF STORY-QUALITY SCORE
5.9/10
Not ready for a Senior PM interview
Simple average of seven story-quality criteria.
PROOF EVIDENCE DIAGNOSIS
- Personal ownership
- Thin
- Real stakes and resistance
- Thin
- Options and tradeoffs
- Missing
- Outcome and consequences
- Strong
- Follow-up readiness
- Missing
The stakes are clear, but resistance is absent.
The outcome is strongly stated, but causality is thin.
The score summarizes overall story quality. PROOF shows where the underlying evidence is strong, thin, or missing.
Taleproof’s 5.9 score and what it would ask nextSee the seven criterion scores, missing evidence, and follow-up questions.ExpandCollapse
Taleproof score breakdown
CLARITY AND DELIVERY
- Immediate comprehension
- 8.5
- Spoken quality
- 6.0
STORY SUBSTANCE
- Tension
- 5.0
- Personal action and action chain
- 4.5
- Result
- 7.5
INTERVIEW SIGNAL
- Seniority
- 5.5
- Memorability
- 4.0
Why Taleproof held it back
THE CANDIDATE’S DECISION IS HIDDEN
The answer says they “created,” “aligned,” and “prioritized,” but never shows the consequential decision they personally made.
THERE IS NO REAL RESISTANCE
Six functions appear to align immediately. The story never shows competing incentives, pushback, or how influence was actually required.
THERE ARE NO OPTIONS OR TRADEOFFS
We never learn which alternatives existed, what was rejected, or what the candidate cut or deferred to ship within five weeks.
THE RESULTS ARE IMPRESSIVE, BUT NOT CAUSALLY EARNED
The metrics sound strong, but the story never establishes which change drove them or how the candidate separated the redesign’s effect from the sales campaign occurring in the same quarter.
What Taleproof would ask next
- When you concluded the onboarding experience was too complex, what specifically in the funnel showed you that? Which step were enterprise users dropping at, and what did the customer feedback say was hard?
- What did you actually remove or change to simplify the experience? What did you decide to leave in or defer to ship within five weeks?
- Across the six functions, did anyone disagree with the recovery plan or your priorities? What was their position, and how was it settled?
- The sales campaign ran in the same quarter as the fix. How did you separate the 27% activation improvement from the campaign’s effect, and how was “activation” defined?
The story does not need better wording yet.
It needs better evidence.
Taleproof would ask these questions before rewriting the answer.
WHAT DO YOU WANT TO EXPLORE NEXT?
Methodology and exact ChatGPT prompt
This is a synthetic Senior PM interview story deliberately written to look strong under conventional STAR criteria while leaving some deeper evidence unstated.
ChatGPT and Taleproof each assessed the exact same story once, without rewriting it first.
ChatGPT was asked to use six conventional STAR criteria: situation and task clarity, STAR structure, concision, specificity, cross-functional leadership, and measurable impact.
Its six criterion scores totaled 52 out of 60, producing an average of 8.67, which rounded to 9 under the prompt’s stated rule.
The Taleproof score shown here is the simple average of the seven criterion scores displayed above.
The PROOF evidence diagnosis shows where the underlying evidence is strong, thin, or missing.
The two scoring systems are not calibrated to the same numeric scale. The comparison shows how they treat the missing evidence differently.
This is one run of one story. It does not describe how every ChatGPT conversation behaves.
You are an experienced product-management interview coach.

This is a conventional first-pass STAR review of a 60–90 second answer for a Senior Product Manager interview.

Evaluate the answer below for this question:

“Tell me about a time you improved an important product outcome through cross-functional leadership.”

Use only these six conventional STAR criteria:

1. Situation and task clarity
2. STAR structure and logical flow
3. Concision and spoken readiness
4. Specificity and use of concrete details
5. Cross-functional leadership signal
6. Measurable impact and result closure

Score each criterion from 1–10.

Calculate the overall score as the simple average of the six criterion scores, rounded to the nearest whole number.

Use these labels:

9–10: Excellent
8: Very Good
6–7: Good
1–5: Weak

Put the overall score and label in the first line.

Then provide:

1. The six criterion scores
2. The three strongest qualities of the answer
3. The single most important improvement
4. Whether you would recommend using this answer in a real Senior Product Manager interview

Assess the answer exactly as written and only against the six listed criteria. Do not rewrite it, ask follow-up questions, or introduce a separate scoring rubric before scoring.

STORY:

At a B2B SaaS company, enterprise activation dropped 18% after a new onboarding launch, six weeks before our largest annual sales campaign. I was asked to lead the recovery without delaying the campaign.

I reviewed the funnel, analyzed customer feedback, and concluded that the onboarding experience was too complex. I brought Product, Design, Engineering, Data, Sales, and Customer Success together, created a recovery plan, aligned the group around a simplified experience, prioritized the highest-impact improvements, and set up twice-weekly reviews to keep execution on track.

We shipped in five weeks. By the end of the quarter, activation had improved 27%, time to value fell 35%, support contacts dropped 22%, and the campaign exceeded its pipeline target. The new flow became the default for enterprise onboarding. The experience reinforced the importance of using customer evidence and clear accountability to align cross-functional teams.
This is the complete prompt as submitted. It deliberately asks for conventional STAR criteria; it is not a neutral rubric.
Sources: OpenAI Memory FAQ · OpenAI — “Does ChatGPT tell the truth?”. ChatGPT is a product of OpenAI. Taleproof is not affiliated with or endorsed by OpenAI. The final screenshot will show a real assessment of the exact story displayed above.